AI Document Verification for International Student Admissions
Document chase-ups are where admissions pipelines die. A document-intelligence pipeline moves verification from a 30-minute manual review to seconds — and catches the quiet failures a counsellor would miss on a tired Friday.
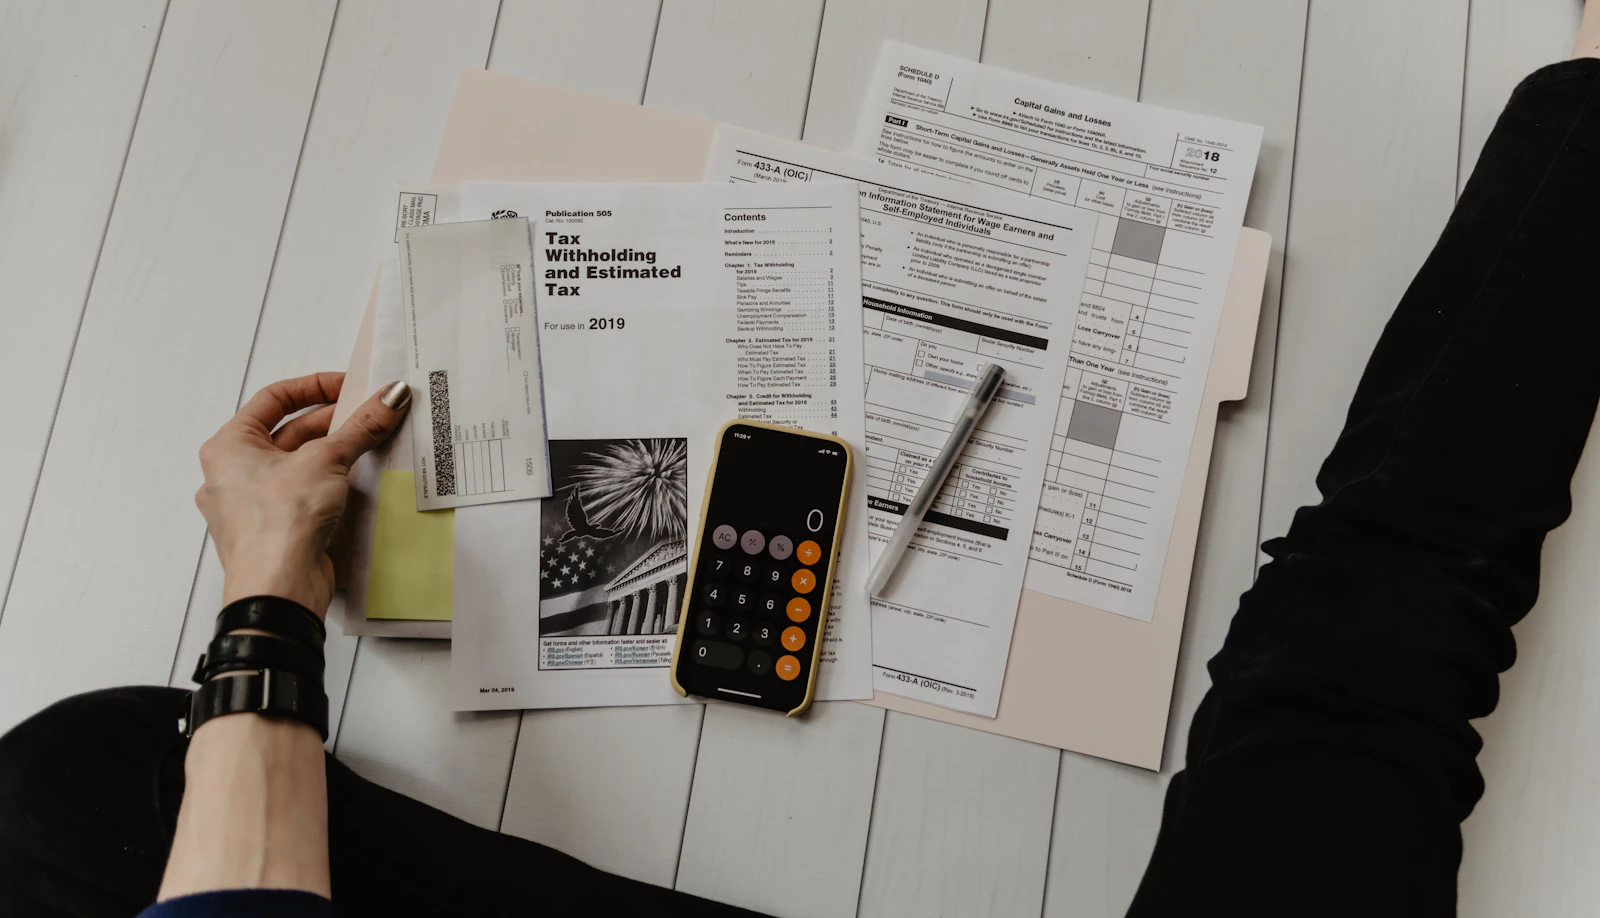
- Document type detection (passport, transcript, English certificate, financial statement).
- Field-level extraction with confidence scoring.
- Name consistency check across every document in the pack.
- Expiry and validity checks (English certificates, passports, bank statements).
- Missing-page detection and page-order repair.
- Counsellor-facing flag queue with reason codes.
- Document vetting on UniCRM.ai moves from a ~30-minute manual review to a ~10-second automated pass (pilot implementation, approved for public display).
- AI document pre-check is a stage inside the UniCRM.ai desk-based workflow, not a standalone product (verified configuration).
Why document verification is the real bottleneck
Every admissions director will tell you lead quality is the top problem. In the data, document vetting is. A counsellor who closes a student at enquiry can still lose them two weeks later when the visa team rejects the pack because a transcript was photographed in portrait with the right-hand margin cut off. The lead was fine. The pipeline failed at verification.
Multiplied across a cohort, this quiet failure is the single biggest reason admissions pipelines produce lower deposits than their enquiry volume should predict.
What the pipeline actually looks like
A production document-intelligence pipeline has four stages:
- Ingestion. Documents arrive via WhatsApp, portal upload or inbox integration. The pipeline normalises format (image, PDF, mixed) and classifies each page.
- Extraction. OCR runs across the normalised stack. A document-specific extractor pulls structured fields with confidence scoring — passport number, DOB, English score bands, transcript grades.
- Validation. Rule-based validation runs: name consistency across every document, expiry checks, page completeness, format conformance to the destination country's visa requirements.
- Review queue. Issues flag back to the counsellor with reason codes — "Transcript missing page 3", "English certificate expired 11 days ago" — not generic "document invalid" errors. The counsellor's job becomes approving the AI's judgement, not re-reading the document.
The failures a human misses
The useful work the pipeline does is not matching the big fields. It is catching the quiet failures that a tired counsellor on a Friday afternoon will skim past:
Each of these is a one-week stall in the pipeline. The pipeline catches them in seconds.
- English certificate expired 11 days ago (visa officer rejects on arrival).
- Passport name order differs between surname-first and given-name-first across documents.
- Transcript photographed with the final column of grades cut off.
- Financial statement from a joint account where the student is not named.
- Date-of-birth mismatch of two days between passport and school transcript.
Compliance, PII and audit
Document intelligence in admissions is a PII-heavy workflow. The right architectural posture is:
The audit trail matters as much as the extraction. When a visa officer asks why an application was submitted with a known issue, the counsellor needs to show that the AI flagged the issue and a human overrode it, not that the pipeline missed it.
- Documents stored in object storage with per-tenant encryption keys.
- Model inference performed with document content, not with client-level fine-tuning.
- Immutable audit log of every automated decision — timestamp, model version, confidence, downstream counsellor action.
- No training on client-identifying data. Verified records never leave the tenant.
How this fits into the admissions CRM
A document-intelligence pipeline is not a standalone product. It sits inside the admissions CRM as a pre-check stage between a student's upload and the counsellor's inbox. The counsellor's view of a student record shows the AI's extracted fields next to the raw documents, flags open, and a single approve/reject control.
On rejection, the pipeline composes the next outbound WhatsApp message — "Hi Ayesha, we need a clearer scan of page 3 of your transcript" — from a tenant-approved template. The student receives the specific ask within minutes of upload, not days.
Frequently asked
Does the pipeline work for every country's documents?
The pipeline needs to be configured per source country for transcripts and per destination country for visa-conformance rules. CloudLab typically ships a UK + Pakistan + India + UAE + Nigeria baseline and extends per client.
What accuracy should an admissions team expect?
On fielded extraction (passport number, DOB, English score band) the pipeline runs well above 95% with confidence scoring. On rule-based validation (expiry, name-match, page completeness), close to 100% because the checks are deterministic — the model is only used for extraction, not for the pass/fail decision.
Is this a replacement for a human visa officer?
No. The pipeline is a pre-check, not a decision authority. Human review happens on every flagged document and on a sampled percentage of clean documents. The pipeline makes the human faster, not optional.
How is the pipeline retrained?
Not on client data. Baseline models are updated against public document corpora. Tenant-specific corrections (e.g. a particular university's transcript format) are handled via rule-based extractors, not model fine-tuning. This preserves the data-residency posture.
Explore the capabilities behind this article.
More from this cluster.
Education recruitment runs on WhatsApp, spreadsheets and desk-to-desk handovers. Here is how a bespoke admissions CRM — with AI counsellor agents, document vetting and desk-based workflow — changes the operational maths of running a consultancy or an in-house university recruitment team.
WhatsApp is where recruitment conversations actually happen. Here is how a WhatsApp-first CRM — with a shared inbox, AI-suggested replies and workspace-level audit — replaces personal-phone chaos with institutional memory.

The useful AI inside a business is not a chatbot — it is the document pipeline. Here is what a production document-intelligence stack looks like, where it belongs inside existing workflows, and how to size an engagement.